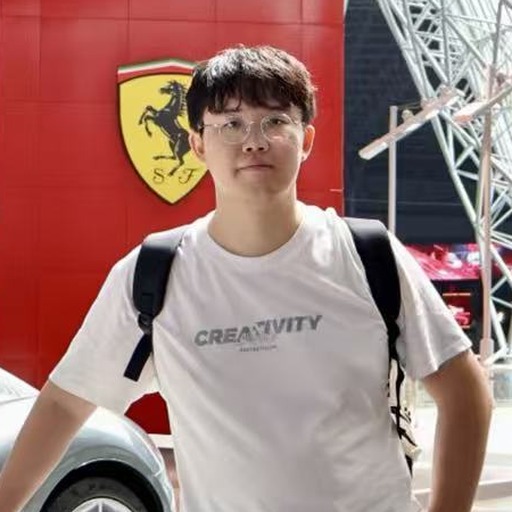
😀 About Me
I am a Ph.D. student in Computer Vision at Mohamed bin Zayed University of Artificial Intelligence (MBZUAI), supervised by Prof. Xiaojun Chang. Before this, I received my master’s degree in Information and Communication Engineering from the School of Information Science and Technology, University of Science and Technology of China (USTC) in 2026, also supervised by Prof. Xiaojun Chang, and my bachelor’s degree in Communication Engineering from the College of Information Science and Engineering, Hohai University in 2023.
My research interests include visual content generation, multimedia understanding and alignment.
🔥 News
- 2026.09: 🎓 Joined MBZUAI as a Ph.D. student, supervised by Prof. Xiaojun Chang.
- 2026.06: 🎓 Received my M.E. degree from USTC.
- 2026.05: 📝 SRC-Flow is released on arXiv.
- 2025.11: 🎉 Token Painter is accepted by AAAI 2026.
- 2025.09: 💼 Joined Kling AI Research, Kuaishou Technology as a research intern.
- 2025.04: 🎉 SDTL is accepted by IEEE TMM.
- 2025.02: 🎉 SmartEraser is accepted by CVPR 2025.
- 2024.08: 💼 Joined Microsoft Research Asia (MSRA) as a research intern.
- 2024.07: 🎉 SEDS is accepted by ACM MM 2024.
📖 Educations
 2026.09 - Now, Ph.D. in Computer Vision, Mohamed bin Zayed University of Artificial Intelligence, Abu Dhabi, UAE.
 2023.09 - 2026.06, M.E. in Information and Communication Engineering, University of Science and Technology of China, Hefei, Anhui, China.
 2019.09 - 2023.06, B.E. in Communication Engineering, Hohai University, Nanjing, Jiangsu, China.
💻 Internships
 2025.09 - Now, Kling AI Research, Kuaishou Technology, Beijing, China.
 2024.08 - 2025.02, Microsoft Research Asia (MSRA), Beijing, China.
 2023.01 - 2023.06, Alibaba, Quark Search Department, Hangzhou, Zhejiang, China.
📃 Publications
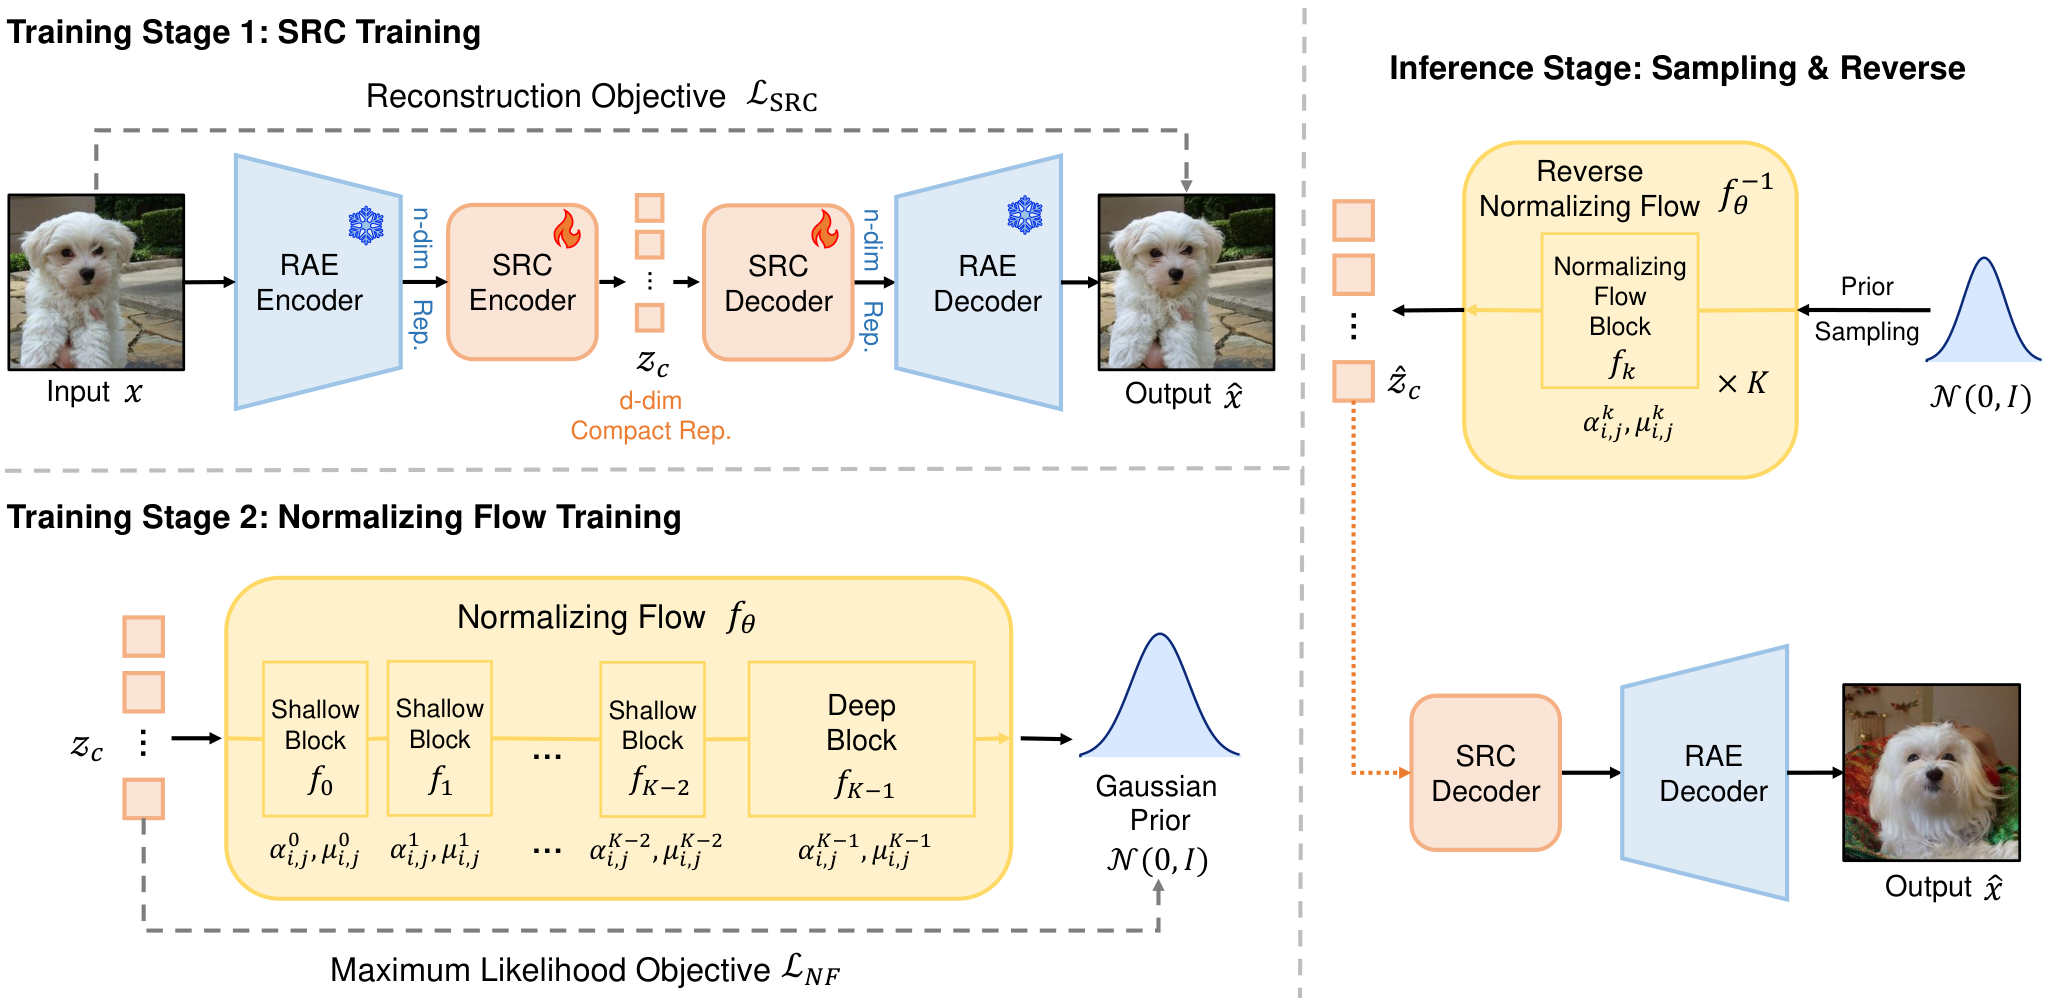
SRC-Flow: Compact Semantic Representations Enable Normalizing Flows for Image Generation
Longtao Jiang, Jianmin Bao, Zhendong Wang, Xin Tao, Zhihui Li, Xiaojun Chang
arXiv Under review
- We identify a semantic-capacity mismatch between normalizing flows and high-dimensional pretrained vision features, and propose a Semantic Representation Compressor that compresses frozen RAE features into a compact 32-channel space for flow modeling.
- With constant noise regularization, SRC-Flow achieves state-of-the-art gFID among normalizing flows on ImageNet 256×256 (1.65) and 512×512 (2.07).
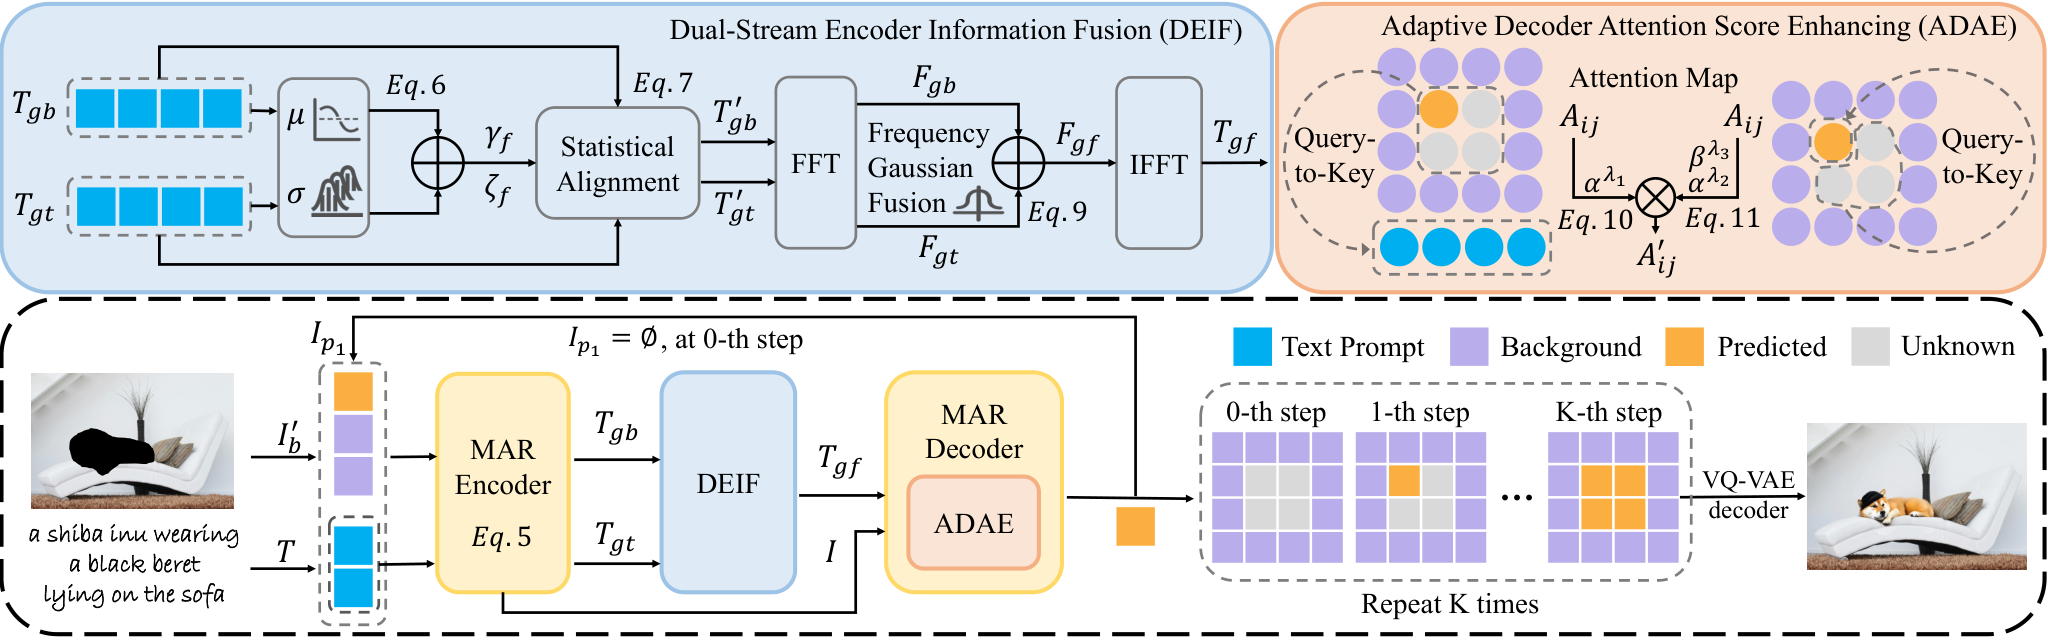
Token Painter: Training-Free Text-Guided Image Inpainting via Mask Autoregressive Models
Longtao Jiang, Jie Huang, Mingfei Han, Lei Chen, Yongqiang Yu, Feng Zhao, Xiaojun Chang, Zhihui Li
- We propose Token Painter, a training-free text-guided image inpainting method built on Mask AutoRegressive (MAR) models.
- A Dual-Stream Encoder Information Fusion (DEIF) module fuses text and background information in the frequency domain to produce guidance tokens, and an Adaptive Decoder Attention Score Enhancing (ADAE) module strengthens attention on guidance and inpainting tokens.
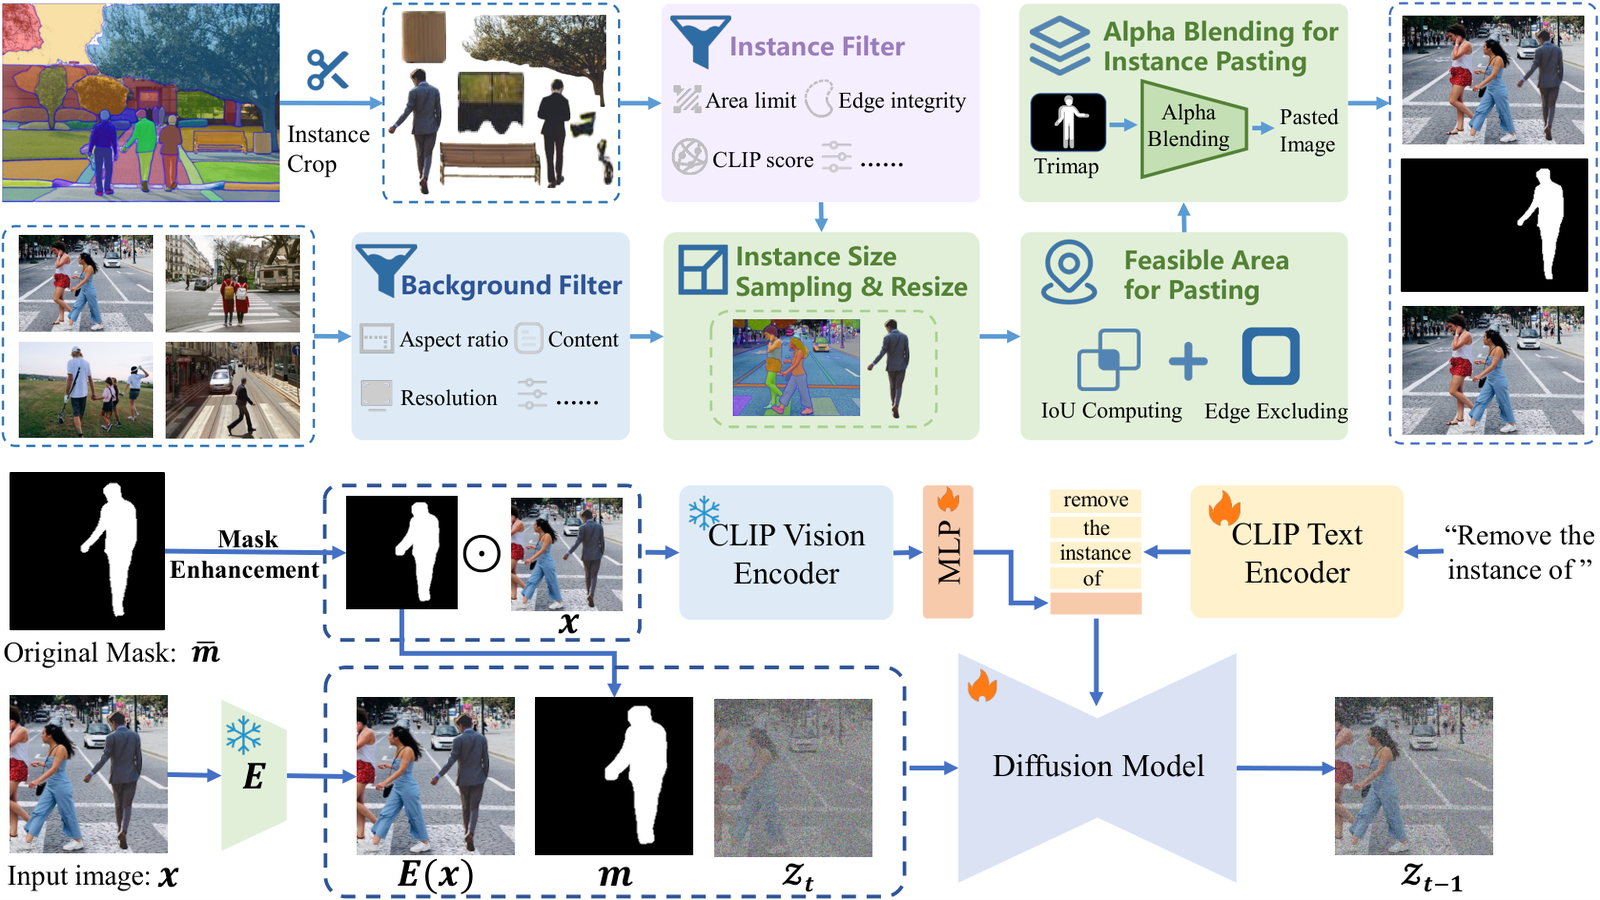
SmartEraser: Remove Anything from Images using Masked-Region Guidance
Longtao Jiang, Zhendong Wang, Jianmin Bao, Wengang Zhou, Dong Chen, Houqiang Li
- We introduce SmartEraser, built with a new “removing” paradigm called Masked-Region Guidance.
- The paradigm guides the model to accurately identify the object to be removed, preventing its regeneration in the output.
- Since the user mask often extends beyond the object itself, it aids in preserving the surrounding context in the final result.
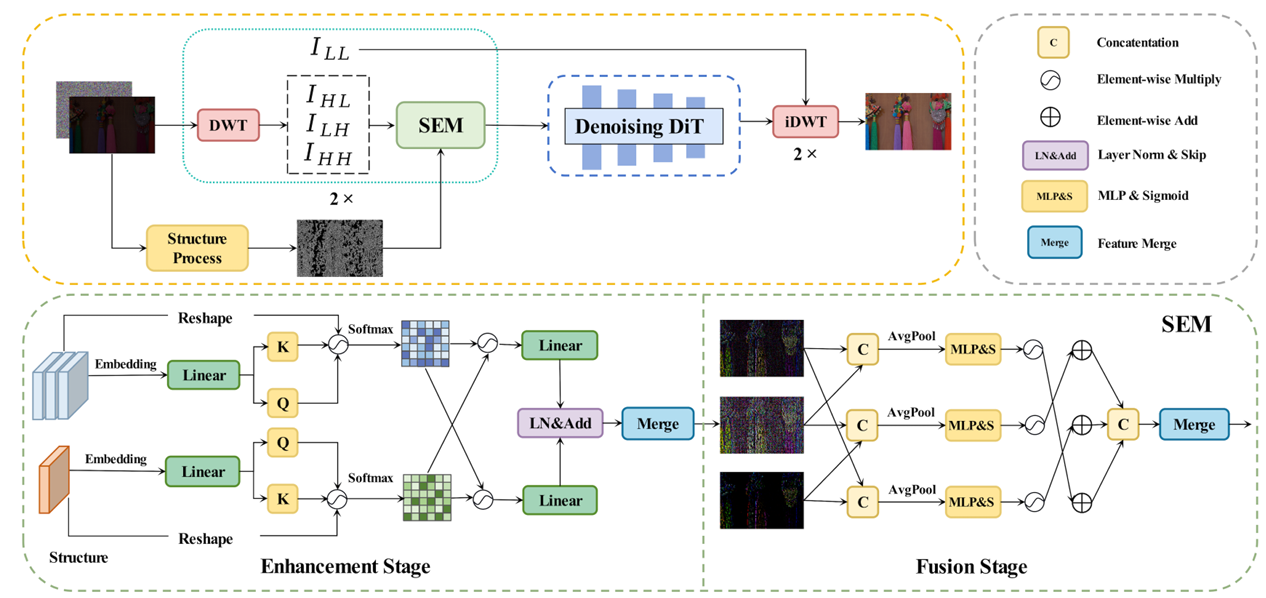
Structure-guided Diffusion Transformer for Low-Light Image Enhancement
Xiangchen Yin, Zhenda Yu, Longtao Jiang, Xin Gao, Xiao Sun, Zhi Liu, Xun Yang
- We introduce DiT into the low-light enhancement task and design a novel Structure-guided Diffusion Transformer based Low-light image enhancement (SDTL) framework.
- Extensive qualitative and quantitative experiments demonstrate that our method achieves SOTA performance on several popular datasets.
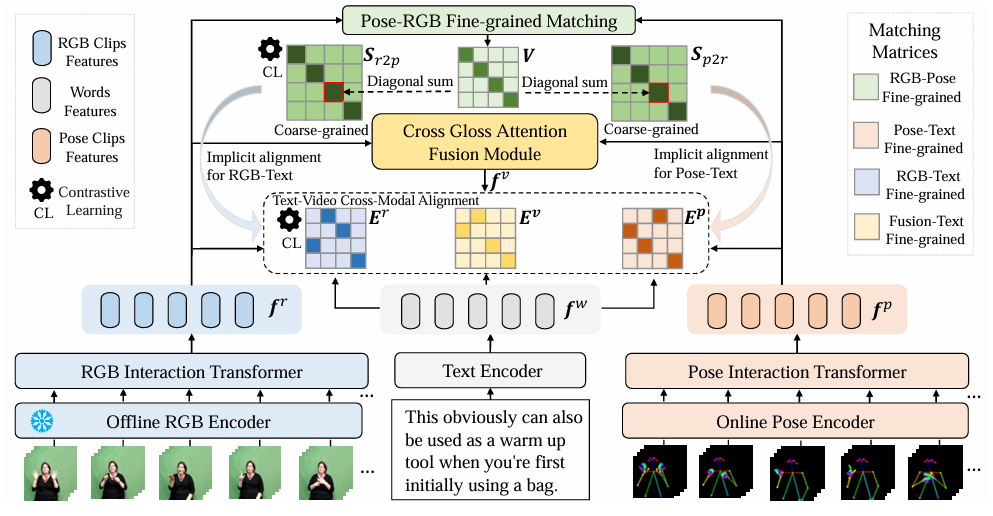
SEDS: Semantically Enhanced Dual-Stream Encoder for Sign Language Retrieval
Longtao Jiang, Min Wang, Zecheng Li, Yao Fang, Wengang Zhou, Houqiang Li
- We propose a novel representation framework called Semantically Enhanced Dual-Stream Encoder (SEDS), which aggregates Pose and RGB modalities to represent local and global information of sign language videos.
- The aggregated clip-level video features are fed into the CLIP vision encoder for interaction, and matched with the word-level text features embedded using the CLIP text encoder.
📝 Academic Services
I serve as a reviewer for top-tier conferences and journals, including CVPR, ICLR, NeurIPS, AAAI, ACM MM, and IEEE TPAMI.
🏅 Honors
- 2026.06, Outstanding Graduate of Anhui Province
- 2026.06, Outstanding Graduate of USTC
- 2025.09, National Scholarship for Graduate Students
- 2024.12, Huawei Scholarship from USTC
- 2023.12, First Class Master’s Scholarship from USTC
- 2023.09, Outstanding Graduate of Hohai University (Top 1%)
- 2023.02, Xiaomi Scholarship Special Prize (Top 1%)
- 2022.10, First Prize of Yan Kai Scholarship (Top 1%)
- 2020.12, Excellent Student Model in Hohai University
- 2020.09, National Scholarship for Undergraduate Student (Top 1%)
- 2020.09, The First Prize Scholarship in Hohai University